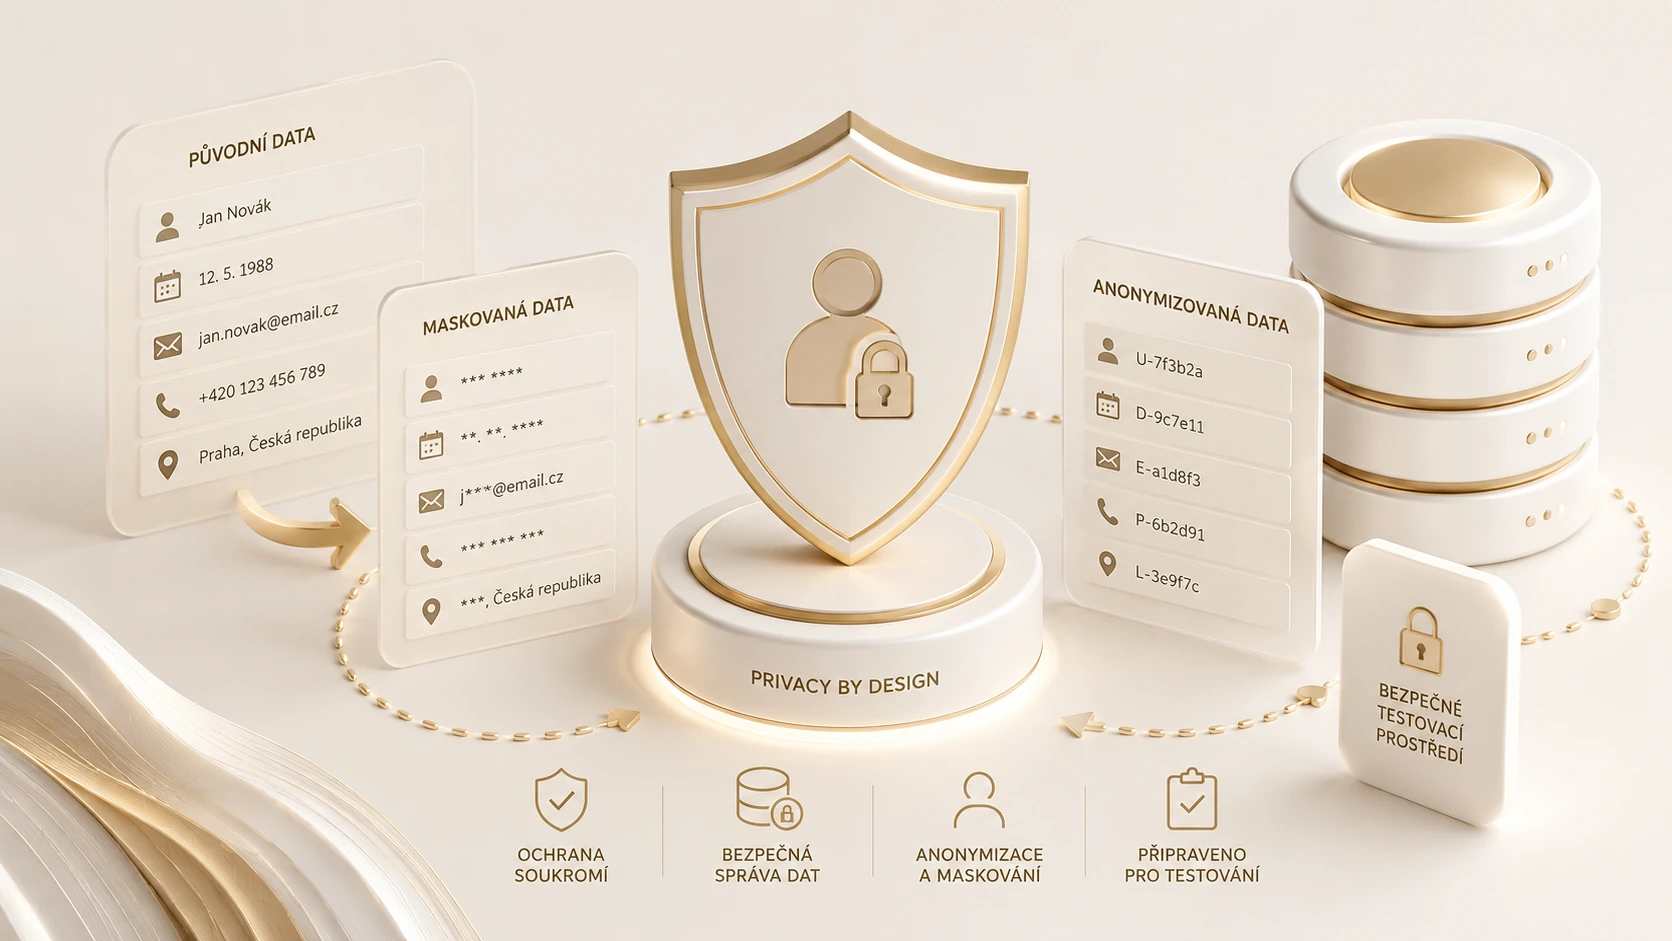
Test data must resemble production sufficiently to expose genuine defects. That does not make a copy of the production database the best starting point. Alongside useful relationships, such a copy may contain names, contact details, payment histories and information irrelevant to the test. The database is only one destination: records may subsequently appear in logs, screenshots, issue attachments and backups. I would therefore design a test’s explanatory power and its information requirements together, rather than decide how to protect an unnecessarily broad copy afterwards.
A documented case: Advanced and supplier responsibility
On 26 March 2025 the UK Information Commissioner’s Office announced a £3.07 million penalty against Advanced Computer Software Group for security failings affecting information about 79,404 people. Advanced supplied IT services to healthcare organisations. The ICO record is not evidence of a test-database breach. I use this documented processor incident to motivate a preventive question about copies and access, not to invent a technical cause.
My question would be whether the organisation can account for every supplier-held copy and explain its purpose. One incident does not establish that all external environments are unsafe. It does justify checking access arrangements, file transfers, deletion responsibilities and the end of the supplier relationship. Calling something a test does not explain why a particular user needs a customer’s full history. A useful inventory should connect each environment with an owner, authorised users, the information it contains and an explicit retention decision.
Realistic does not mean identical
A test may require a long surname, a missing field, an unusual character or several contracts belonging to one customer. It rarely requires a real person’s actual surname. I would distinguish technical format, statistical properties and business relationships. Import testing depends on field length and encoding; segmentation depends on category distribution; reporting depends on stable identifiers and valid links. These requirements can be specified without automatically carrying over identity. Any exception should be justified against the particular test question rather than accepted as a default convenience.
Replacing names alone is insufficient when a combination of location, age, employer and an unusual event can identify someone. I would not automatically describe a pseudonymised dataset as anonymous. Actual anonymisation requires an appropriate assessment of the circumstances. My analytical contribution would begin by reducing columns and records and explaining their purpose. That makes the problem smaller before the more specialised legal and security questions are considered. It also makes accidental inclusion easier to notice because the expected contents are explicit rather than inherited from a database export.
A hypothetical regression dataset
Suppose I need to test an import of 100,000 customer records and the resulting number of active contracts. A functional dataset could contain thirty synthetic customers: a customer without a contract, one with several contracts, an ended contract, missing contact information, a duplicate and varied name formats. A separate performance dataset could generate 100,000 synthetic records with the same schema. Identifiers would be artificial while referential relationships remain valid. I would calculate expected totals before execution, independently of the application’s own answer.
I would deliberately include five invalid relationships and three duplicates. The test must establish whether the system rejects, flags or transforms them according to the agreed rule. An anonymisation process that automatically cleans every invalidity would remove important test conditions. Dataset documentation should therefore describe the meaning of the exceptions as well as the row count. The performance data also needs sufficient variation: repeating an identical row may create unusually favourable caching behaviour and give an unrealistic impression of capacity. Volume alone is not a realistic workload.
How I would organise the data journey
I would start with the test questions and map each to essential fields. I would then choose a generation method and verify that it preserves the relationships on which the application makes decisions. Before use, I would confirm access rights, permitted environments and retention with the relevant data owner and security team. The record should identify who generated the dataset, the generator version and its parameters. A generator change modifies the evidence supporting a test and should be reviewed accordingly, rather than treated as an invisible implementation detail.
Outbound connections deserve a separate check. A test address or phone number must not contact a real customer. Payment and communication integrations should use appropriate test modes or controlled substitutes. An access token is sensitive even when the associated records are artificial, so a token inside an example export remains a separate defect. Before transferring a spreadsheet, I would check hidden worksheets, comments and attachments. A filename containing the word anonymous is not evidence that the file is safe, nor does a password remove the need to minimise its contents.
Defect evidence should contain only what is needed
I would attach the smallest example that reproduces the issue. If a synthetic record identifier and an expected count suffice, the full export adds exposure without explanatory value. For screenshots, I would consider surrounding panels and open tabs as well as the highlighted error. For logs, I would check whether contacts or secrets leak through error messages. Safe testing therefore extends beyond database preparation to the evidence a tester creates whenever a problem is found. A useful bug template can encourage this without making reproduction unnecessarily difficult.
Deletion should not mean only executing a database command. I would consider backups, exports, local folders and confirmation that access has ended. For repeatable tests, a short-lived generated dataset may be simpler than a permanent copy requiring continuous maintenance. A failed deletion should have an owner and resolution date rather than disappear as a minor technical issue. I would also check restoration procedures: restoring a backup should not silently reintroduce a dataset whose approved retention has ended. The lifecycle needs to remain understandable even when environments are rebuilt.
I would also check whether the next person can repeat the safe preparation without informal instructions. A documented route is useful only when the approved data and necessary access are actually available.
Summary and recommendations
A strong test dataset answers the test question reliably while containing only necessary information. I would recommend starting with synthetic records, independently validating relationships and exceptions, and restricting production copies to justified situations. Every dataset should have a known origin, purpose, authorised audience and removal date. I would also measure how many defects can be reproduced without production information. That provides a practical indicator of safer, more repeatable testing rather than merely counting how many files have been labelled as protected or anonymised.