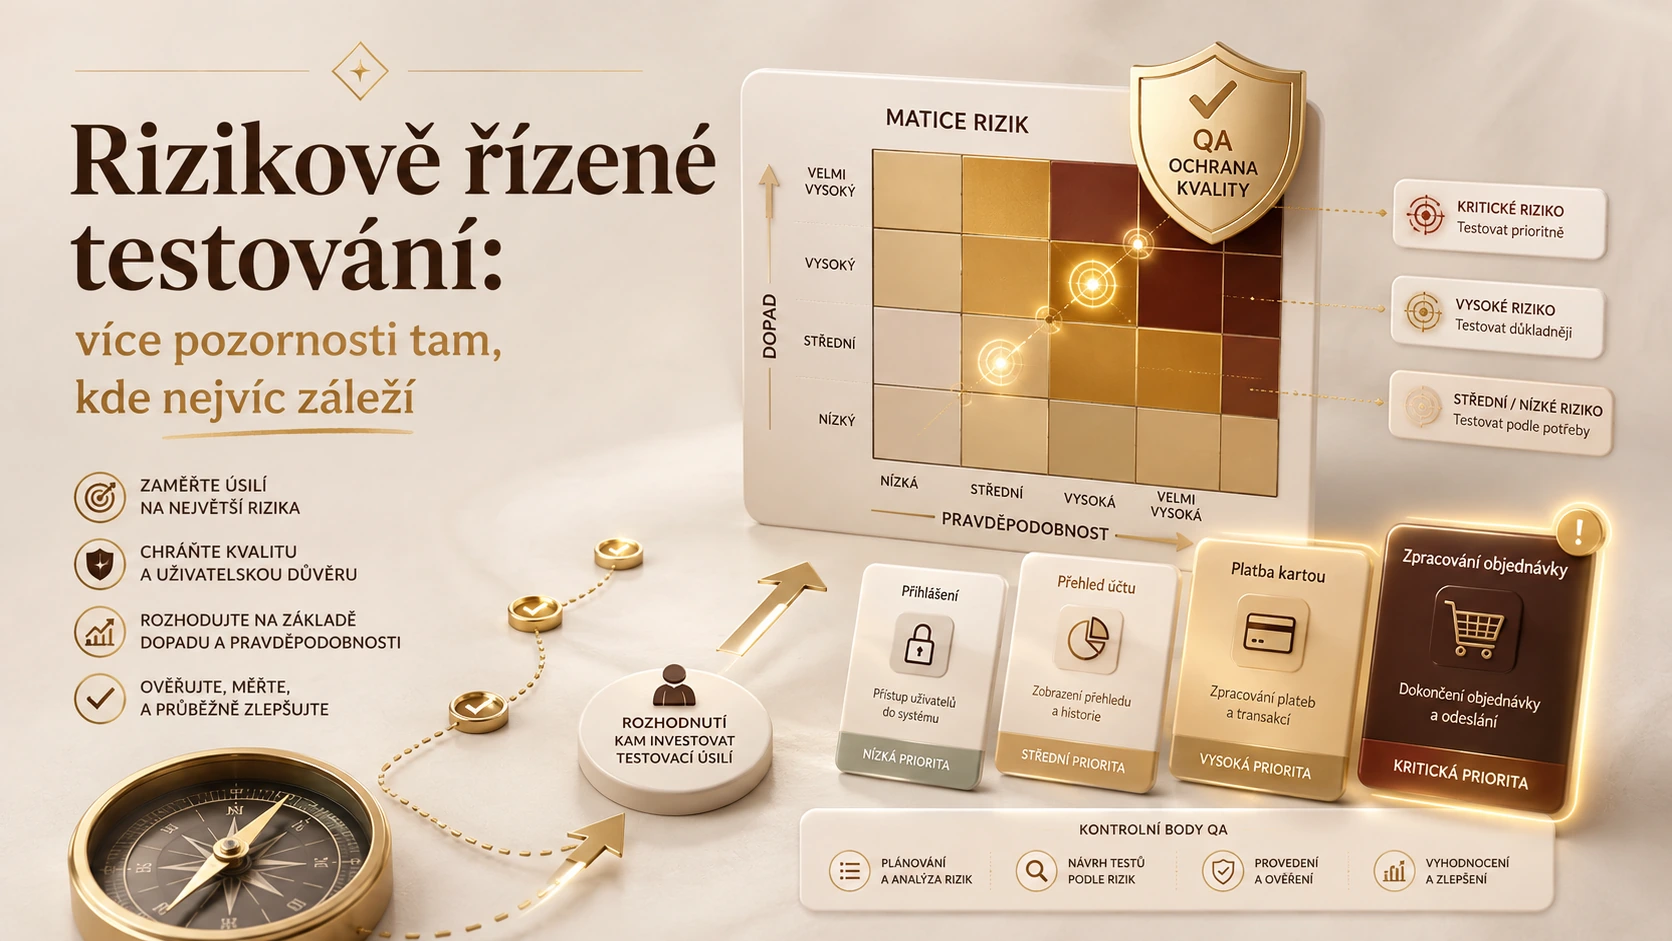
Testing time should not be allocated evenly
When time is limited, every feature cannot receive equal attention. To me, risk-based testing means explaining why one situation receives deeper examination and which uncertainty remains. It does not mean declaring the rest of the application unimportant. It is an ongoing allocation decision based on potential impact, likelihood, the scope of change and the ability to detect and contain failure.
Two equally small code changes in a banking application can carry very different risks. Editing paragraph spacing and altering instalment rounding may each involve one line, but they affect different outcomes. Lines of code and counts of test cases are therefore insufficient measures of safety. I would need to understand the operation and the downstream use of its result before recommending priorities.
A documented case: Knight Capital, United States, August 2012
In its 16 October 2013 action, the SEC described Knight Capital's incorrect deployment of trading code. On 1 August 2012, the resulting activity generated large numbers of unwanted trades and a substantial loss. My focus is how deployment and controls can amplify a software defect. This was a securities-trading case, not a Czech lending rule. [1]
I would resist the convenient claim that one additional test would necessarily have prevented the event. Counterfactuals need evidence too. The case can nevertheless inform precise questions: which deployed components are active, what limits unintended operations and how quickly will someone recognise a departure from expected behaviour? That moves the discussion from general diligence towards specific protective layers.
A hypothetical loan application change
Imagine a release changing the calculation of a charge on an early repayment. Only five percent of loans use that branch, but an error can directly change the amount requested from a customer. The same release changes a confirmation button's colour for everybody. The button's greater exposure does not automatically justify giving it more analytical time than the sensitive calculation.
For the calculation, I would test boundaries, effective dates, zero outcomes and the transfer into documents and accounting records. For the button, I would check readability, usability and accessibility. Both need attention, but different depth and evidence. This charge is entirely hypothetical; it is not a statement of the legal rules governing early repayment in any jurisdiction.
Construct a defensible priority order
I would first work with the process owner to identify outcomes that could materially harm customers or the institution. For each, I would describe the affected result, triggering conditions, population and existing controls. A numerical score can support discussion but should not conceal uncertainty. Multiplying subjective ratings does not produce an exact estimate of financial-loss probability.
I would then trace the change through the data and system journey. A definition altered at a source can affect several reports whose code has not changed. An unclear dependency or unknown downstream use would be a reason to investigate scope before declaring a low priority. An unfamiliar area is not automatically the riskiest, but missing knowledge must not be mistaken for reassuring evidence.
The discussion should also distinguish frequency from consequence. A rare error affecting an important financial decision may warrant more attention than a frequent inconvenience with a safe workaround. Decisions can differ legitimately between services, provided that the reasoning is documented and the accountable owner understands the trade-off being accepted.
Test beyond the ordinary path
For a priority operation I would include interruption, failure and repetition. What happens if the connection breaks immediately after a save? Can the system recognise an already processed request? How does it handle a missing input? Correct results during an ideal journey do not cover a customer repeating an action because no confirmation arrived. For financial operations, that ambiguity can be significant.
I would also examine whether the test can actually recognise the wrong result. An automated check for the presence of a page does not verify an amount. The expected value needs an explainable basis. If the expectation uses the same incorrect rule as the implementation, a passing test can create unjustified confidence. Sensitive cases benefit from an independent calculation or another separately established comparison.
Test data need to support the selected risk. A boundary scenario cannot be assessed if every sample falls comfortably in the middle of the permitted range. I would therefore connect dataset selection to the reason for each test rather than use convenient records merely because they already exist. The trace from risk to input to expected result should remain understandable.
Respond honestly to time pressure
As the deadline approaches, I would not hide unfinished work behind a broad coverage percentage. I would present verified risks, unresolved questions and possible release restrictions. Reducing scope or rolling out progressively may help. Sometimes the relevant message is that a material calculation has not been adequately checked and the decision requires an appropriately accountable owner.
A deferred test should have a reason, owner and review date. Otherwise a list of exceptions becomes forgotten debt. If the same area is deferred repeatedly, I would ask whether the obstacle is the data, environment or an unclear requirement. Risk-based prioritisation should expose such barriers, not become a permanent justification for leaving them unresolved.
Learn from the outcome
After deployment I would compare observed problems with the original assumptions. A defect in an area rated low risk may reveal missing information or a mistaken weighting. One event does not necessarily invalidate the method, but it can identify a factor to include next time. Retrospective adjustment should improve future choices rather than rewrite the old assessment so that it always appears correct.
I would likewise avoid equating defect counts with testing value. A priority control that consistently protects an important function without finding defects may remain worthwhile. Its value depends on the risk and evidence it provides, not an expectation that every execution must discover a failure. Changes in the service or environment can alter that judgement over time.
Summary and recommendations
Risk-based testing directs limited time towards outcomes that matter for reliable decisions and customer protection. I recommend linking priority risks to specific tests, independent expectations, protective layers and named owners of unresolved uncertainty. Changes in priority should be explainable, especially when deadlines create pressure to accept incomplete evidence.
NIST's SSDF provides further reading on demonstrable software verification practices. [2] My analytical contribution would connect business impact, data relationships and the actual testing evidence. The objective is not a promise of defect-free software. It is a clear explanation of why the selected checks are proportionate and where further verification or an explicit decision is still needed.