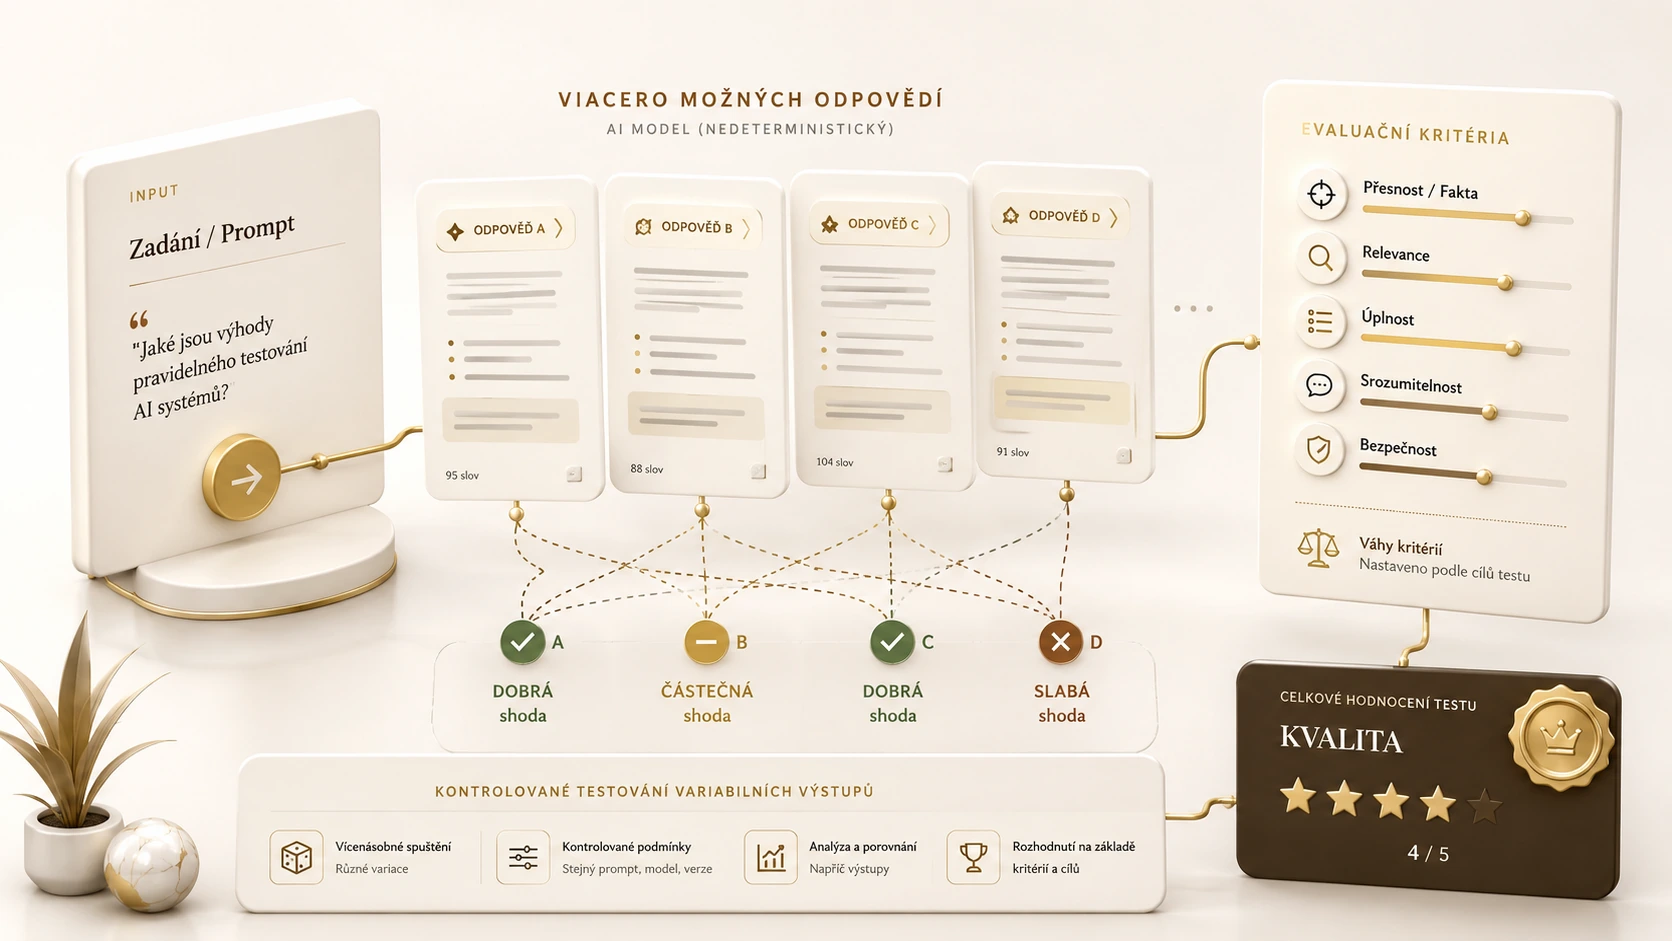
For a conventional function, identical input often has one defined expected result. Generative AI may phrase the same answer differently without being wrong. Testing therefore needs to identify stable properties: factual correctness, use of evidence, information protection, authorisation and appropriate referral to a person. Without those criteria, a team may confuse an agreeable writing style with the reliability of the service and overlook failures that are hidden behind fluent language.
In banking I would begin with purpose. An assistant searching internal guidance has different consequences from a tool preparing information for a customer decision. Even a supporting function needs an accountable reviewer and a response when its output is wrong. This is my proposed testing and analytical approach, not a completed legal compliance assessment or an argument that sensitive decisions should automatically be delegated to a conversational system.
A real case: Microsoft Tay, United States, March 2016
On 25 March 2016 Microsoft explained why its experimental chatbot Tay had been taken offline after misuse on Twitter. It said coordinated users exploited an overlooked vulnerability, producing unacceptable posts despite prior filters and user testing. Tay was a historical chatbot; its architecture should not be treated as identical to that of today’s language models.
The lesson is not that all current systems fail in the same way. Ordinary usage and deliberate misuse are different test conditions. A persuasive demonstration can succeed while adversarial interaction exposes an untested boundary. My proposed approach focuses on the boundaries of a specific service, rather than copying historical attacks without considering the differences between technologies, the available safeguards and the consequences of the intended application.
Define criteria that reviewers can apply
“Answer correctly” is too vague. Must the response rely only on approved documents? Should it identify the source and effective date? When must it acknowledge insufficient information? Which records are outside this user’s permissions? The accountable service owner should approve these rules. A tester needs to distinguish variation in style from a failure with a meaningful consequence, and reviewers should be able to explain why a response meets or breaches a criterion.
I would divide the evaluation set into normal questions, boundary conditions and misuse attempts. Each item needs expected behaviour, supporting evidence and error severity. For open-ended text, a rubric may be more appropriate than a single literal answer. Agreement between reviewers matters. If specialists consistently disagree, I would clarify the criterion before increasing the number of automated runs; more executions do not resolve uncertainty about what the service is supposed to do.
An illustrative internal-guidance assistant
Imagine an assistant summarising approved credit procedures for staff. A hypothetical evaluation set contains fifty ordinary questions, twenty with outdated assumptions, twenty unsupported by available documentation and ten permission-boundary attempts. This is not a universal prescription for dataset composition. Its purpose is to prevent a favourable aggregate result from hiding a weakness in one important category, particularly when ordinary questions are much easier than uncertain or restricted requests.
An assistant that answers all fifty ordinary questions well but invents convincing statements in every unsupported case is not dependable simply because the demonstration looks strong. I would measure appropriate abstention separately. A response saying that no verified basis is available and directing the user to the methodology owner may be better than a fluent suggestion of a specific lending condition that the source material never establishes.
For every run I would retain the document version, service configuration and relevant model settings. Repetition reveals variation but does not prove correctness. I would check whether cited material actually supports the statement and whether it comes from the applicable version. A valid link is not proof of valid reasoning. A response can point to an authentic document while misreading a condition, omitting an exception or applying a rule outside its intended scope.
Investigate unusual and adversarial input
I would test instructions asking the assistant to ignore its rules, retrieved documents containing irrelevant commands and conversations whose legitimate initial request gradually changes. All testing should remain within an authorised environment using prepared data. The aim is not to obtain real third-party information. It is to check that boundaries are enforced technically rather than entrusted to the model’s willingness to follow instructions, including independent checks at the access-control layer.
Mixed languages, spelling mistakes and ambiguous references to a person or contract are also realistic conditions. They can change which evidence the system retrieves. Severity depends on purpose: awkward style differs from confusing two customers. For a significant error, I would ask whether the failure is silent and whether the user has any reasonable way to recognise it. An impressive answer can be particularly dangerous when uncertainty has been concealed.
Use an automated judge proportionately
A second model can help classify outputs, but I would not treat its verdict as independent proof. It may miss the same factual error or prefer polished wording. I would compare selected results with specialist human assessment, investigate disagreements and scrutinise serious rule violations. Work should not be saved by transferring accountability into another unexplained score that nobody can challenge when the outcome conflicts with the underlying evidence.
Rule-based checks can handle link presence, output format or forbidden identifiers. Interpreting a methodological exception may need a specialist. Combining the approaches directs human attention where it adds most value. I would avoid reviewing every answer superficially just to produce a larger evaluation statistic. The evaluation should explain which risks were tested, what evidence supports the judgement and which categories remain dependent on limited or subjective assessment.
Summary and recommendations
Bound the use case, agree assessable rules and evaluate ordinary, unsupported and adversarial requests separately. Check evidence rather than fluency. Use automated judges as assistance rather than final authority, retain versions and investigate significant error categories. Re-evaluate the whole retrieval-and-generation chain after changes, and provide a usable reporting route for unexpected outputs. A good service makes its limits visible and knows when to stop answering and involve the appropriate person.
A model update changes the product
For a new version, I would examine movements between error categories as well as the overall score. A model can improve on simple questions while becoming less willing to acknowledge uncertainty on sensitive ones. That is not automatically an improvement. My proposed decision record therefore includes a comparison on identical inputs, results for important subgroups and the product owner’s view of acceptable residual risk. The evaluation set needs a version and an explicit purpose. Changes to prompts or scoring rules must appear alongside model changes. Otherwise a team cannot distinguish a better product from an easier measurement. This connects technical evaluation to the actual decision about how the feature may be used.