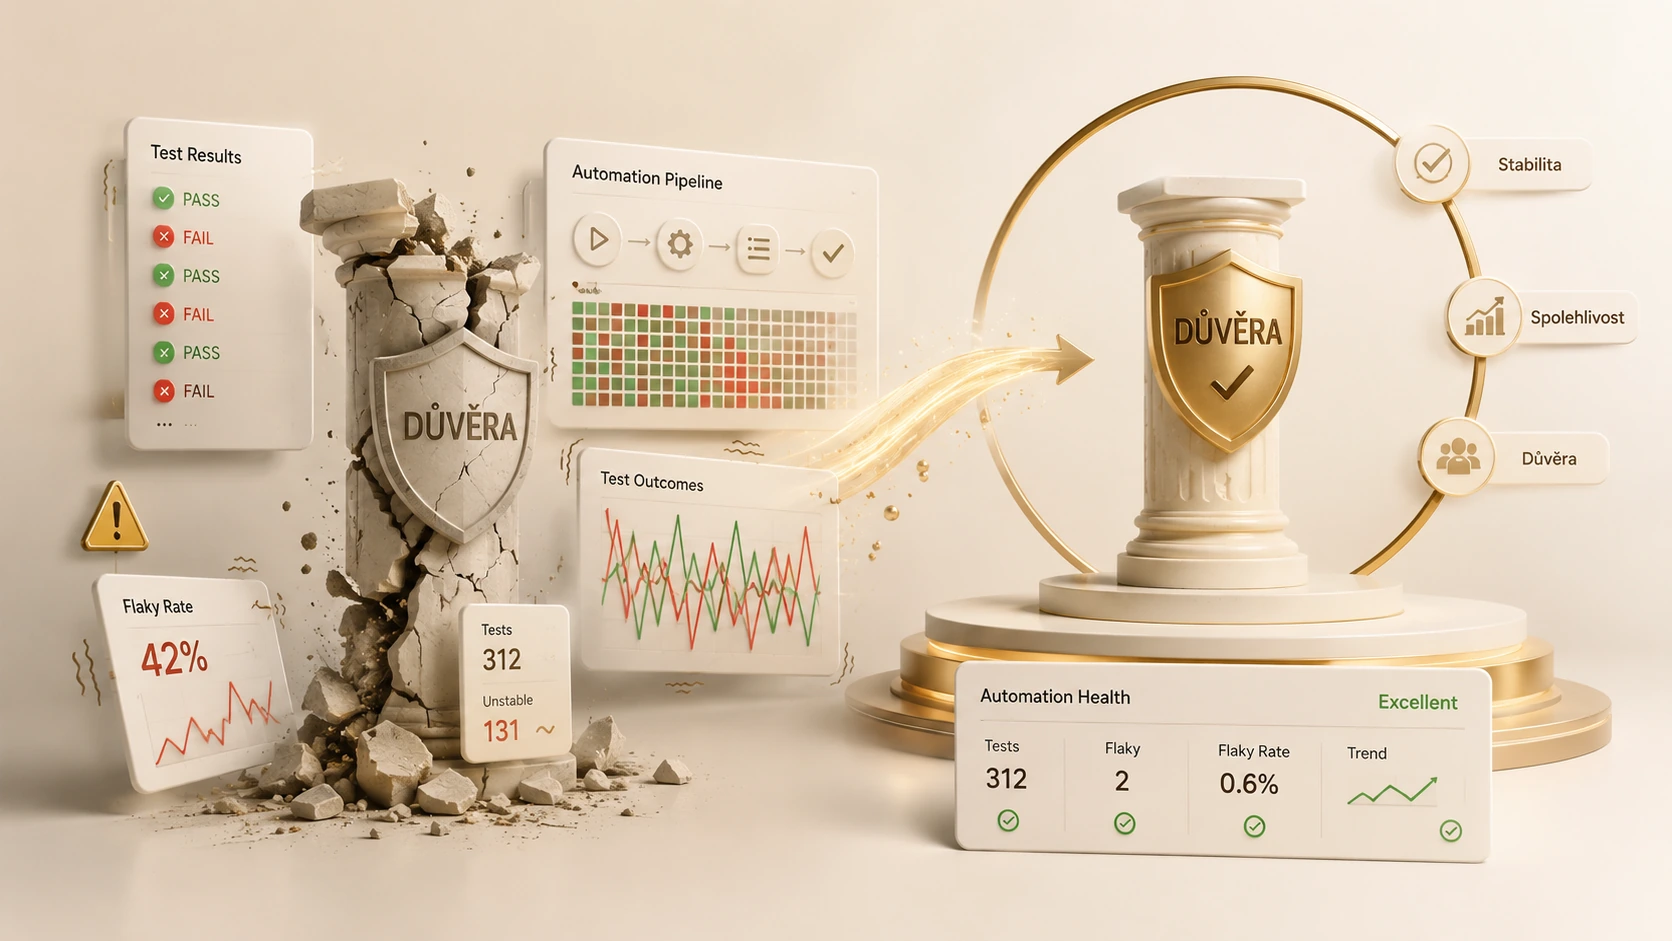
A test should help determine whether a change has broken something. When identical code produces a pass and then a failure, that signal becomes difficult to use. The cost is not limited to waiting for another run. Teams learn that a red result may mean nothing and can overlook a genuine regression. I therefore treat flaky behaviour as a defect in the overall testing system that needs evidence, prioritisation and an accountable investigation.
In a banking or data-sensitive application, instability can complicate validation of payments, imports and calculations. It would nevertheless be wrong to blame the test automatically. Intermittent failure may expose a real concurrency defect or an unsuccessful recovery after connection loss. Before classifying a failure as noise, I want to understand which conditions changed between executions and whether the expected behaviour is actually defined clearly enough to support that judgement.
A documented example: Google, May 2016
On 27 May 2016 Google’s testing blog reported flaky outcomes in approximately 1.5% of test runs and some level of flakiness in almost 16% of tests. These are historical observations from that organisation, not universal benchmarks or current measurements for every project. The report also discussed how repeated false alarms undermine trust.
The relevant lesson for my proposed approach is the decision problem. If every red run is expected to be a false alarm, the next real defect can be missed. Those historical percentages cannot establish an acceptable level elsewhere. I would need local execution history, the significance of protected functions and the time spent investigating. The following recommendations are my analysis, not a description of Google’s current internal practices.
Measure conditions, not impressions
I would record the test, code version, environment, time, input data and failure signature. A count of unsuccessful executions alone cannot distinguish a product regression from instability. Transitions between pass and fail under the same stated conditions are more useful. Grouping results by suite and dependency can reveal that ten failing functions share one overloaded environment rather than represent ten independent product defects requiring separate investigations.
Evidence from the first failure must survive a rerun. A browser trace, service log, request identifier and timeline may contain information that disappears during the next execution. Repetition has diagnostic value but should not silently overwrite the original result. The report should show that the first attempt failed and the next passed, rather than present a clean build that conceals uncertainty from the person making the release decision.
An illustrative case: concurrent campaign creation
Suppose twelve of one hundred controlled executions fail to find a newly created campaign in a list, although creation was acknowledged. All tests use the same account and campaign name. The system and figures are hypothetical. I would distinguish delayed list refresh, colliding data and a genuinely missing record before making a change. Each explanation implies a different investigation and a different way of showing that a correction works.
Adding ten seconds might hide some failures without explaining them. I would use the identifier returned by creation, isolate each run’s data and provide safe cleanup. For an asynchronous update I would wait for an observable condition within a justified limit. A slow response is not automatically acceptable: the relevant requirement must establish its tolerance. A test should reflect that expectation rather than move the deadline until the result looks reassuring.
I would compare serial and parallel execution separately. If serial execution succeeds, shared state becomes a useful hypothesis, not proof that the test is at fault. The test might reveal a genuine product concurrency issue. I would therefore change data isolation and waiting logic in separate steps. Combining both immediately makes it harder to explain which action addresses the observed behaviour and whether an unresolved risk remains hidden.
Prioritise the protected behaviour
An uncertain payment-approval check carries different significance from a cosmetic check on a secondary page. I would consider the impact of the protected behaviour, frequency and investigation cost. If an unstable automated scenario is temporarily removed from a release gate, a critical function needs dependable alternative verification. Removing the gate does not remove the risk or establish that the underlying application works correctly under the conditions that were previously uncertain.
Temporary quarantine needs an owner, a cause or stated hypotheses, an alternative check and a review deadline. The test can continue to collect diagnostic information while its release-blocking effect is explicitly separated. I would not want a permanently ignored list growing without oversight. Reviewing newly quarantined and genuinely repaired cases prevents the issue disappearing behind a large overall count of tests and apparently favourable pass percentages.
Recreate the conditions that mattered
After a correction I would repeat the relevant original conditions. Concurrency-related failure needs concurrent verification; a time-zone or midnight issue needs those combinations. Zero failures in a limited sample is not mathematical proof of absolute stability. I would state the execution scope, retain the evidence and continue normal monitoring. A short period without recurrence can be useful information without justifying a stronger claim than the sample supports.
I would also improve the explanation available when the next real failure occurs. A stable test that returns only a generic timeout still creates expensive diagnosis. Clear checkpoints can distinguish an unaccepted request, unfinished processing and an undisplayed outcome. That reduces unnecessary reruns and makes future defects easier to investigate. The quality of a test includes the quality of information it provides when the product genuinely stops meeting its requirement.
Summary and recommendations
Preserve the first failure, measure instability under identifiable conditions and repair causes rather than rerunning indefinitely. Prioritise according to the protected function’s risk. Give any quarantined test an alternative check and a route back into normal use. Confidence grows when a team understands what a failure means, how to investigate it and what uncertainty remains. A larger number of green icons cannot provide that understanding on its own.
Who approves a test’s return
In my proposed process, leaving quarantine should require more than a sequence of green runs. The repair needs an explanation of the instability mechanism and evidence that the revised test still separates correct from incorrect behaviour. For concurrency, increasing a delay is insufficient: control the relevant event sequence and observe the actual completion condition. A reviewer should also check whether the repair weakened the original assertion. A test that no longer checks anything important has not been repaired successfully. I would record the original cause, the change and remaining limitations for every intervention. This creates reusable knowledge and helps decide whether the test still belongs in a fast blocking suite. The decision should include the cost of missed defects, not only the reduction in pipeline failures.