Why this matters
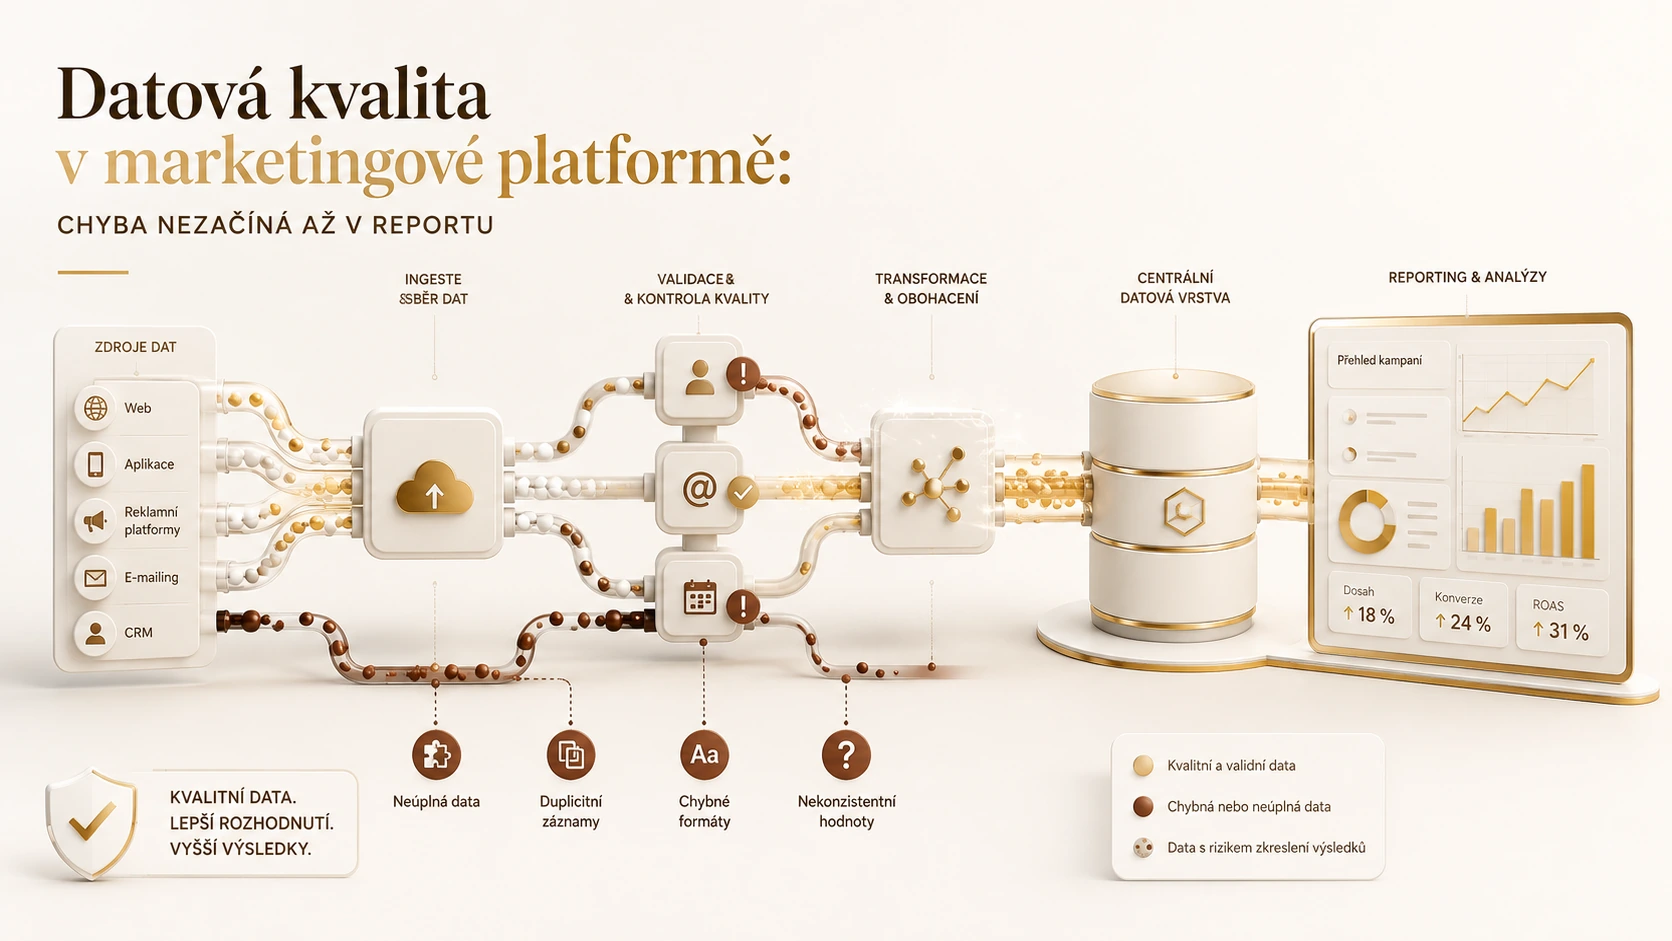
Marketing data travels through a chain of systems and rules. A report may be mathematically correct and still misleading because records were duplicated, timestamps shifted or consent attributes lost earlier in the pipeline.
Quality must therefore be observed at each hand-off, with clear ownership and reconciliation between stages.
How to do it well
Map the data journey
Document sources, transformations, storage, segmentation and destinations, including owners and schedules.
Define critical data rules
Specify required fields, allowed values, uniqueness, time zones and business invariants.
Validate at ingestion
Reject or quarantine malformed records and record why they failed.
Reconcile transformations
Compare counts and totals before and after each meaningful transformation.
Monitor freshness and drift
Alert when expected feeds are late, volumes change unusually or value distributions shift.
Trace a record end to end
Maintain identifiers and audit information that allow one record to be followed through the pipeline.
What to avoid
- Checking only dashboards after the data has already influenced decisions.
- Using row count as the only quality measure.
- Silently replacing invalid values with defaults.
- Mixing time zones or deduplication rules across systems.
- Leaving failed imports without an owner and recovery process.
Hypothetical practical example
A campaign report shows fewer recipients than expected. End-to-end tracing reveals that an import normalised phone numbers differently, causing duplicate detection to merge valid contacts.
A useful control compares source count, accepted count, rejected count, segmented count and exported count, with explicit reasons for every difference.
Lesson for practice
Data quality is a property of the whole journey, not the final table. Early validation, reconciliation and traceability prevent small upstream errors from becoming confident downstream decisions.
A good practice does not have to be complicated. It should be intentional, repeatable and explainable: the team should understand why the control exists, what evidence it provides and how feedback will improve the next iteration.
A real case: trust also depends on access
On 17 January 2023, Mailchimp reported a security incident involving 133 customer accounts and unauthorised access to a support and account-administration tool. The affected setting was the online Mailchimp platform. This was not an established deduplication defect. I use it here to illustrate why platform trust also involves access and change controls.
Data quality and security are different disciplines. A correctly calculated recipient list can be disclosed improperly, just as a securely stored list can contain incorrect information. I would connect these perspectives without confusing them. A reconciled contact count does not establish correct permissions, and a successful permission check does not validate segmentation rules or the freshness of the underlying information.
A hypothetical example: consent is not just another column
Imagine an invented batch containing 1,000 contacts. The source marks 700 as active consent, explicitly records withdrawal for 200, and has no known state for 100. Our hypothetical business rule allows only the first group into a particular campaign. This is not a legal assessment of a real campaign; its applicable basis and circumstances would need separate specialist consideration.
If import processing replaces unknown values with “yes,” the output may contain 800 recipients while remaining technically valid. The column contains only permitted values and the email addresses have valid syntax. Schema validation alone will not detect the mistake. The original meaning of missing information, the effective time of a state and the rule selecting the authoritative record all need to be preserved.
A delayed withdrawal message creates another problem. If the person changes their state after segment creation but before campaign activation, expected behaviour at that boundary must be defined. I would build a test around that precise interval, checking the source record, transfer and state at the time of activation. Simply recounting the segment at the beginning of the workflow would not establish the final result.
How I would allocate responsibilities
The process owner confirms state definitions and usage rules. Developers demonstrate transmission and processing. QA validates agreed examples and reproduces discrepancies. This allows the team to discuss a particular rule rather than pass responsibility for “bad data” between functions. Some questions belong with legal or security specialists; an analyst should not replace their assessment with a technical assumption.
For an integration, I would document what the destination’s acceptance means. It may confirm only that a batch has been received for processing, rather than that every record has been stored successfully. Checks should distinguish sent, accepted, rejected and ultimately used records. Retries after interruption deserve attention: a repeat request may continue legitimately, but it may also duplicate records or restore an obsolete state.
Validation after correction
The regression set would include the original failure, an unknown value, withdrawal, a change inside the relevant time window and a repeated import. It should also retain valid records that must not be rejected by the fix. Every example needs a clear expected result and a confirmed rule owner. Otherwise correcting one issue can introduce a different discrepancy that is less visible to the team.
For ongoing monitoring I would propose a compact view of unexplained differences between processing steps, unknown-state proportions, unprocessed-change age and repeated errors by source. Metrics need an explicit population and period. An improving percentage may be misleading when millions of valid records dilute the measure while the same smaller group of customers continues to experience the unresolved problem.
Matching counts can still hide different records
A missing eligible contact and an extra ineligible contact can cancel out in the total. I would compare identifiers and relevant states, not only aggregate counts. Recording when a change was received, when the segment was created and when activation occurred helps distinguish incorrect logic from legitimately different snapshots. Without that timeline, a newer source can make a correct earlier output appear wrong.
Summary and recommendations
I would validate meaning, timing and permitted use alongside data format. Control totals should help explain differences between stages rather than merely record that differences exist. A valuable remediation enables the team to account for an individual record and repeat the investigation after a later integration change. That turns technical validation into practical support for a reliable business process.
Sources and links
- Mailchimp — Information About a Recent Security Incident, 17 January 2023
- GOV.UK — Government Data Quality Framework, 2020
Foreign cases provide analytical lessons; their legal frameworks and measures are not automatically applicable to Czech banks. Hypothetical examples and proposed methods do not describe inspections I personally conducted.