Why this matters
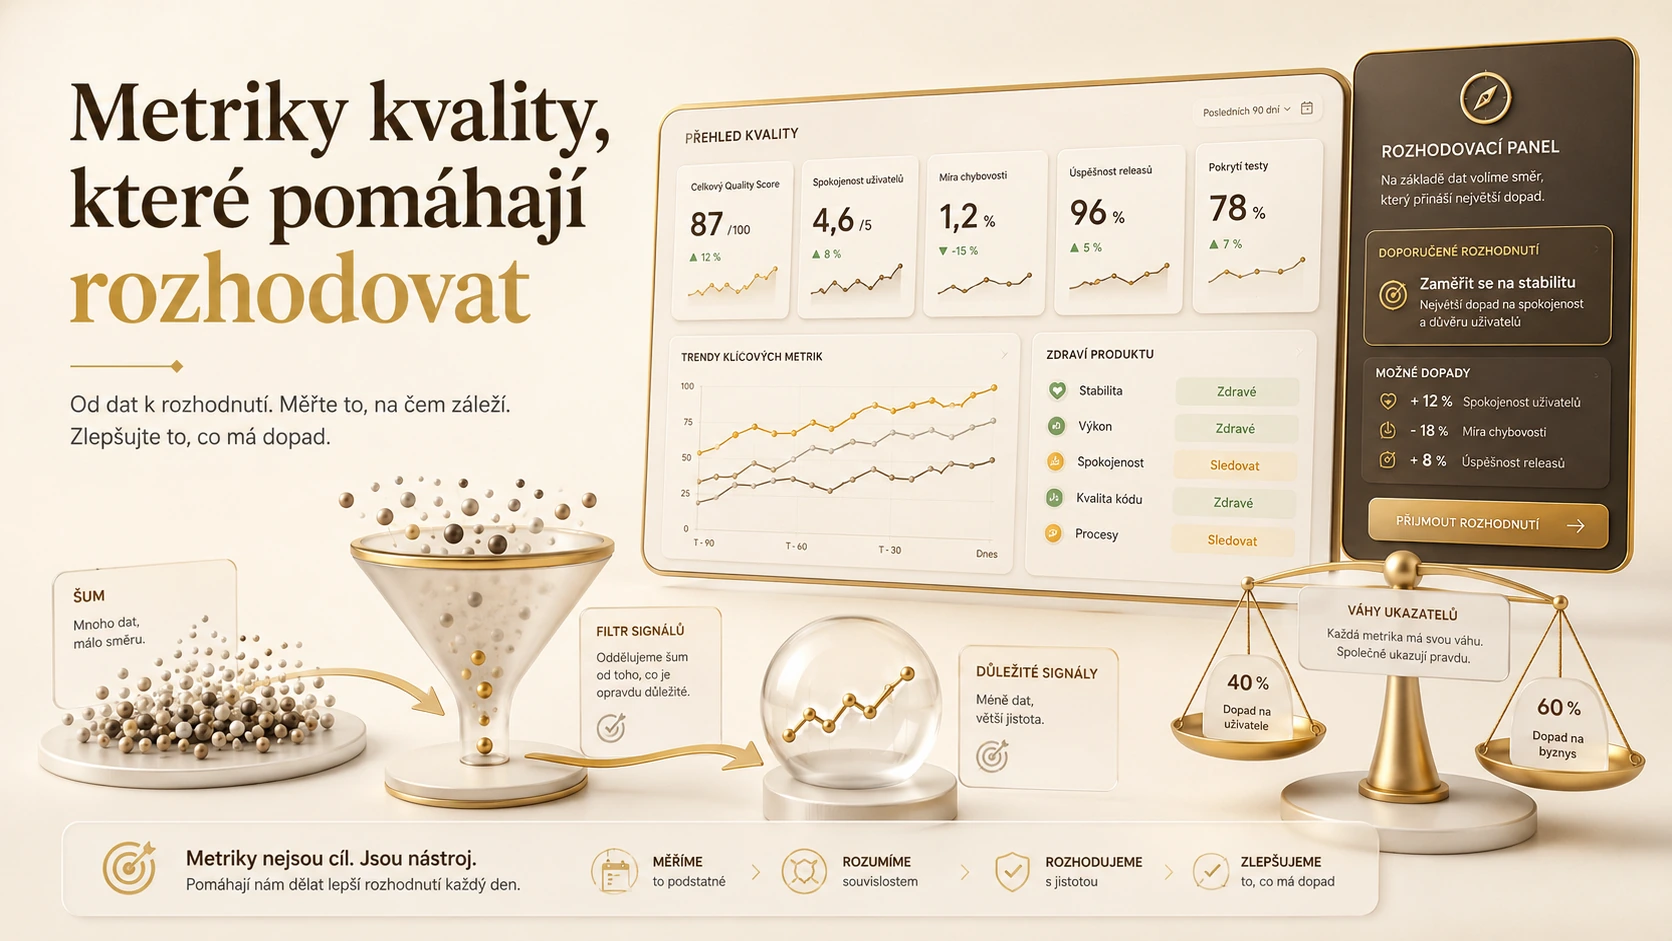
Metrics can create clarity or merely create activity. A useful quality metric connects a question to a decision: where risk is rising, whether feedback is faster or whether users experience fewer failures.
Counts need context, trends and segmentation. Otherwise teams optimise what is easy to measure rather than what improves outcomes.
How to do it well
State the question
Examples include whether releases are becoming safer or whether defect feedback is arriving early enough.
Choose a balanced set
Combine production impact, escaped defects, change failure, test reliability and feedback time.
Define every metric
Document formula, source, owner, exclusions and expected interpretation.
Segment the data
Break results down by product area, risk level or release type instead of relying on one average.
Review trends and outliers
Use changes over time and investigate unusual cases rather than rewarding a single target.
Retire unhelpful metrics
Remove measures that do not change decisions or that drive harmful behaviour.
What to avoid
- Treating more test cases as automatically better quality.
- Comparing teams with different products and risk profiles.
- Using defect count without severity, origin or opportunity to detect.
- Turning a diagnostic metric into an individual performance target.
- Collecting dashboards that nobody uses for decisions.
Practical example
A falling defect count may mean better quality, less testing or fewer releases. Combining it with production incidents, test scope and change volume gives a meaningful picture.
Time from code change to reliable feedback often reveals more improvement opportunity than the total number of automated tests.
Lesson for practice
A quality metric earns its place when it changes a decision. Clear definitions, context and balanced indicators prevent numbers from becoming targets detached from product value.
A good practice does not have to be complicated. It should be intentional, repeatable and explainable: the team should understand why the control exists, what evidence it provides and how feedback will improve the next iteration.
A real case: an order that passed some of the controls
On 22 May 2024 the UK Financial Conduct Authority published its decision concerning Citigroup Global Markets Limited. A mistaken entry on 2 May 2022 created an equity basket worth USD 444 billion. Controls stopped only part of it, and unwanted sales worth USD 1.4 billion reached European markets. These are the regulator’s reported facts, rather than a case from my own employment.
My analytical question would not simply be how many controls existed. I would ask which control was supposed to prevent an excessive order reaching execution, and how its effectiveness was measured. A large blocked volume might appear reassuring while an unacceptable remainder still passes. This is my general interpretation of the control problem, not an additional finding about the firm. It illustrates the difference between counting control activity and protecting the intended outcome.
A hypothetical dashboard that needs a denominator
Consider two versions of a loan application system. The first records 40 defects in a month and the second only 25. The second seems better until we learn that the first processed 20,000 applications and the second 5,000. The respective rates are two and five defects per thousand applications. Even these rates are incomplete: five cosmetic issues and five incorrect instalment calculations do not carry the same consequence.
I would distinguish defects by the decision affected, recoverability and duration of customer impact. I would separately record cases where an incorrect outcome escaped an automated check. I would not call a change in the indicator an improvement until I had confirmed consistent populations and recording rules. Otherwise an apparent reduction might merely reflect a change in classification, a shorter reporting period or fewer opportunities for a defect to appear.
How I would build a decision-focused set
I would start with a concrete decision: can we safely release the revised application form? That calls for evidence about critical journeys, unresolved severe defects and the results of relevant changes. Each metric would have an owner, a defined source, a reporting window and a response rule. Another analyst should be able to reproduce the figure and explain its scope, even if they ultimately recommend a different action.
For automated tests I would distinguish passing on the first attempt from passing after repeated retries. An apparently green pipeline can conceal instability in the most important scenario. Alongside execution speed, I would examine the time needed to understand a failure and the proportion of failures leading to a genuine product correction. These measures help decide whether to expand the suite or first repair the test infrastructure and improve diagnostic evidence.
For banking reports I would likewise separate the number, materiality and age of control exceptions. A rise in detected inconsistencies might follow wider coverage rather than deteriorating source data. Comparisons should therefore retain the population checked and the version of the validation rule. I would accompany a trend with a short explanation of changes instead of expecting a coloured status indicator to convey the whole assessment.
Checking whether the measurement is dependable
Before using a metric in a release or risk discussion, I would ask another person to reproduce it on a small sample. Boundary cases matter: a reopened defect, missing severity, an incomplete reporting day or two incidents sharing one cause. Next I would apply the proposed measures to previous decisions and ask whether they would have highlighted the problem that actually mattered. A measure that cannot influence any action may belong in an operational record rather than an executive decision pack.
The set also needs a clear response to missing data. I would never silently treat an unknown classification as a low-severity issue. It should remain visible as an uncertainty with a named owner and a date for clarification. If the population changes between releases, I would show both the old and new scope for a transition period. This prevents a reporting improvement being confused with a product improvement.
Team incentives need equal attention. A target to reduce recorded defects can discourage honest reporting. I would prefer shared attention to impact, recovery and recurring causes over ranking individuals by defect counts. Transparent identification of a problem is valuable work. The purpose of the measure should be to guide a useful conversation, rather than create a reason to suppress inconvenient evidence.
Summary and recommendations
Choose a small set of indicators and write down the decision and possible response for each before building the dashboard. Define the denominator in every ratio, compare equivalent time windows, and preserve the severity distribution behind a total. My central question would be whether the figures help us do something differently. Metrics support judgement; they cannot replace specialist assessment, prove that an unobserved risk does not exist or remove the need to explain uncertainty.