Why this matters
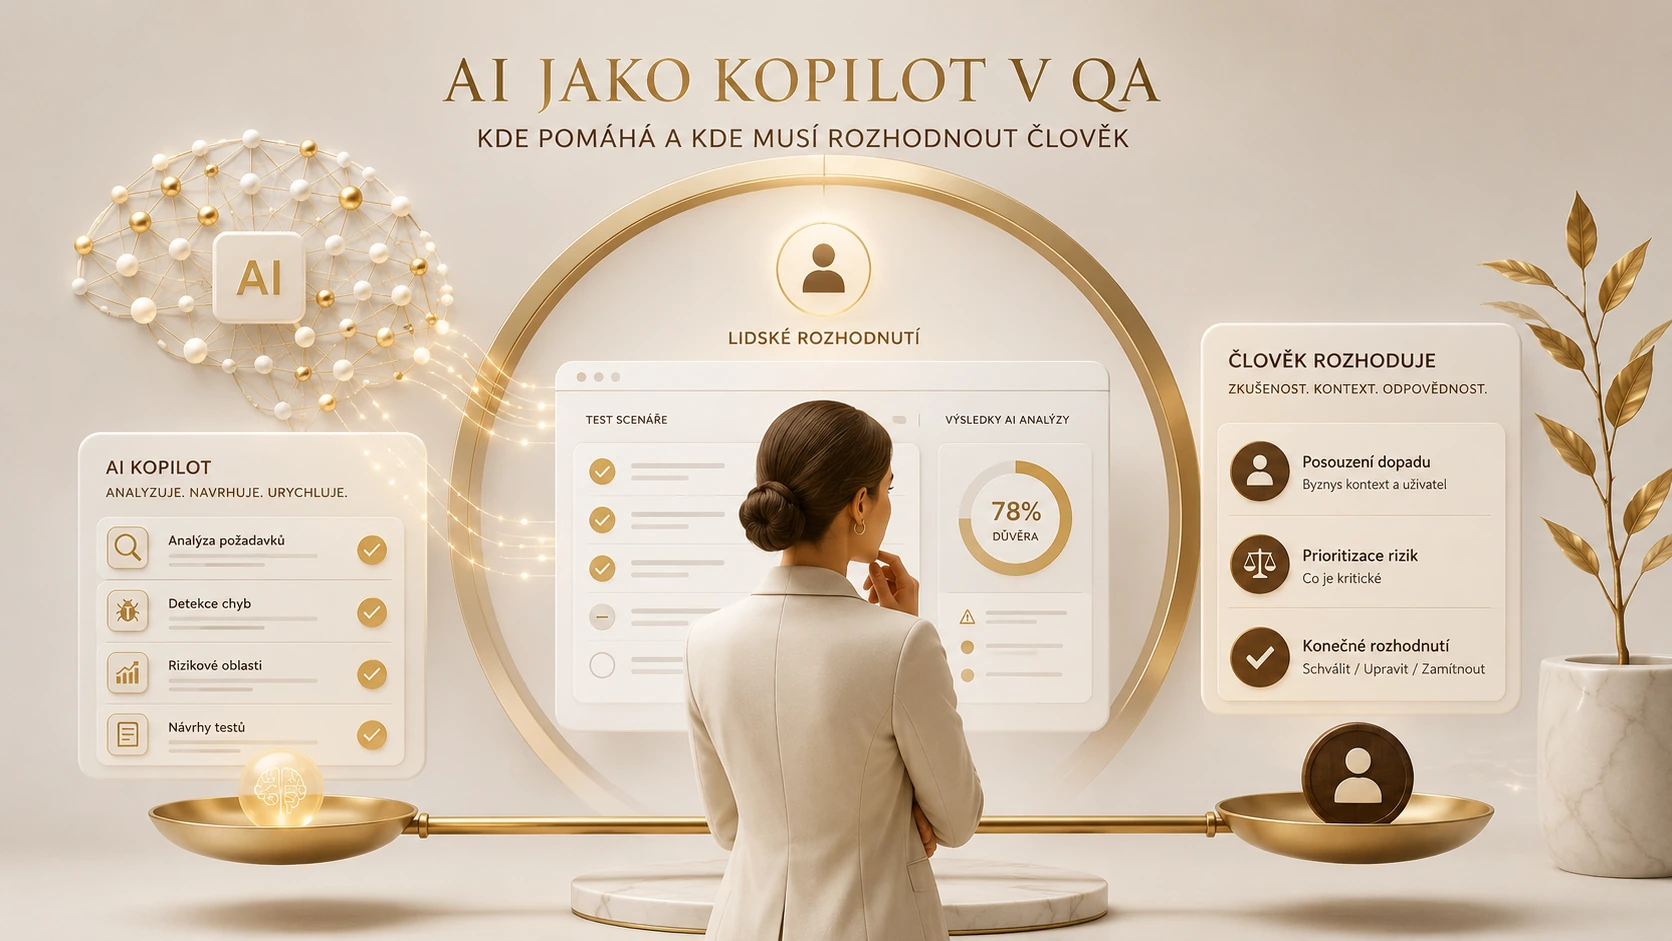
Generative AI can propose test scenarios, summarise long logs and rewrite a technical defect description in seconds. Speed, however, can create a false sense of correctness. In Quality Assurance, the most useful role of AI is not to make the final decision, but to broaden the tester’s perspective and accelerate work with alternatives.
A strong QA professional treats AI as a copilot: the task is clearly bounded, relevant context is supplied, assumptions are requested, and the output is checked against the product, documentation or observed system behaviour. Accountability for the conclusion remains with a person.
How to do it well
Define the task and expected output
Replace “test this feature” with a precise request, such as proposing boundary scenarios for contact import, grouping them by risk and listing assumptions.
Protect sensitive information
Do not paste personal data, tokens, complete production logs or confidential source code into an unapproved tool. Use anonymised examples and synthetic data.
Provide domain context
Describe product rules, target users, constraints and known exceptions. Without context, the result may be generally plausible but irrelevant to the real workflow.
Ask for alternatives and assumptions
Request what the model is assuming, what it does not know and which other explanations are possible. This makes confident but weak answers easier to challenge.
Verify against evidence
Compare important claims with requirements, logs, data, API responses or a reproducible test. AI may identify a useful lead, but it can also invent missing detail.
Record the human decision
Separate AI suggestions from confirmed conclusions in tickets and test records. State what was verified, what remains a hypothesis and who accepted the decision.
What to avoid
- Copying generated test cases without checking the real business process.
- Sharing sensitive data with a tool whose storage and privacy conditions have not been approved.
- Declaring a root cause from a log summary without reproduction and technical evidence.
- Using vague prompts that produce long but low-value lists.
- Measuring success only by time saved rather than accuracy, completeness and rework.
Hypothetical practical example
For a campaign-export failure, AI can group anonymised log fragments into possible categories such as data, authentication, provider limits or transformation errors. QA then verifies the request timeline and the actual API response.
The same approach works for regression design: AI creates an initial list, while QA refines it using incidents, usage analytics and business risk. The outcome should be a better selected test set, not simply more tests.
Lesson for practice
AI creates the most value when it expands human capability rather than disguising missing knowledge. Good practice combines a well-scoped task, safe data, source verification and an explicit human decision.
A good practice does not have to be complicated. It should be intentional, repeatable and explainable: the team should understand why the control exists, what evidence it provides and how feedback will improve the next iteration.
A real case: a pleasing answer was not a sufficient test
On 29 April 2025, OpenAI announced that it had reverted a GPT-4o update because of overly agreeable behaviour. Its 2 May explanation also discussed gaps in detecting that risk before deployment. The affected setting was the online ChatGPT service. This is a documented ChatGPT development case, not a project I worked on.
My takeaway is to ask whether a test actually measures the intended quality. A popular answer may indicate a pleasant tone or convenience without establishing factual correctness. In QA I would distinguish the usefulness of a suggestion, the validity of its assumptions and its ability to expose a defect. This is my interpretation of the lesson, rather than an additional claim about the provider’s internal processes.
A hypothetical task: AI suggests import checks
Consider a synthetic input file containing 200 rows. Twenty lack a required identifier, ten repeat an existing contact and five contain an invalid date. My first question would be whether these groups overlap. Without knowing that, subtracting all exception counts from the total would be unsafe. This apparently small question can separate an impressive test list from an analysis that is actually usable.
I would ask AI to propose scenarios for each group and combinations of conditions. However, I would calculate the expected accepted population independently using the agreed business rule. If the same model creates the data, the expectations and the verdict, the exercise risks becoming circular. Shared assumptions can reinforce one another without anyone checking whether those assumptions are correct.
A single row might lack an identifier and contain an invalid date. I would want to know whether the application reports both errors, reports the first one or rejects the row without explanation. Any of those behaviours might fit a particular specification, but it should be consistent and understandable. I would therefore translate AI suggestions into observable conditions rather than accept scenario titles alone.
How I would assess the actual benefit
I would select a small set of known requirements and anonymised historical defects. Some tasks would use the ordinary process; others would include AI assistance. I would record not only initial drafting time but correction time, missed risks and assertions that could not be verified. Saving ten minutes of writing is not very valuable if the subsequent review takes an additional half hour.
A colleague who did not know how each proposal was produced could review the results. That would not be a scientific experiment, but it could reduce enthusiasm bias around a new tool. I would pay particular attention to confidently wrong suggestions: a test built around a nonexistent product feature, an invented field definition or advice to ignore an exception. Professional wording can make such mistakes harder to notice.
What belongs in the working record
For a consequential use, I would retain the relevant instruction version, tool, date and a short record of human verification. This does not require archiving every conversation. The purpose is to explain how an important conclusion was reached and why it was accepted. If a model or instruction changes later, the team can compare behaviour against the same example instead of relying on memory.
Before using banking or customer information, I would establish the approved conditions for the tool. Removing a name does not necessarily make an input safe when the remaining details still identify a person or transaction. Scenario design often needs only a structural description and entirely invented records. Better context and clearer definitions can provide more value than uploading a larger volume of material.
Summary and recommendations
I would begin with one bounded task, an independently established expected result and a record of the corrections needed. AI can broaden the alternatives considered, but it should not be both the sole author of a test and its only judge. I would assess success through better coverage of meaningful risks and clearer evidence for the team, rather than the length of a generated checklist.
Sources and links
- OpenAI — Sycophancy in GPT-4o, 29 April 2025
- OpenAI — Expanding on what we missed with sycophancy, 2 May 2025
Foreign cases provide analytical lessons; their legal frameworks and measures are not automatically applicable to Czech banks. Hypothetical examples and proposed methods do not describe inspections I personally conducted.